Oscar Craven
Who’s looking?

The page reorders for you. Links keep your choice.

Work

The Tenants’ Voice

Tenancy guidance in plain English, for renters in England.

Live since October 2025Funded build on staging, launch planned December 2026

The short version

What it is
A free website that explains tenancy rights in plain English. It also drafts letters and call notes.
Who for
Renters in England. The funded build adds social-housing tenants.
What I did
I built it and I run it. I turned LSE’s workshop findings into the build plan.
What happened
700+ uses in its first months. Then £113,631 of public funding in April 2026.

Uses: mid-October 2025 to the funding bid, counted from the site’s analytics and quoted in the bid. Funding source: Social Housing Innovation Fund.

What I’d change
Ask fewer questions before giving advice. Testing showed what clarify-first costs.

Two minutes? Read the five lines, then look at the product.

The Tenants’ Voice logo
The funded build on a desktop: language picker, install button, accessibility settings and an Exit this page button.
The funded build on staging, October 2026.

What a tenant can do

Describe the problem. Read your rights. Then act on them.

The chat, with a tenant describing mould and the assistant replying, beside a list of recommended actions.
Describe it in your own wordsThe chat explains your rights and suggests next steps. This shot is from before the October 2026 rename.
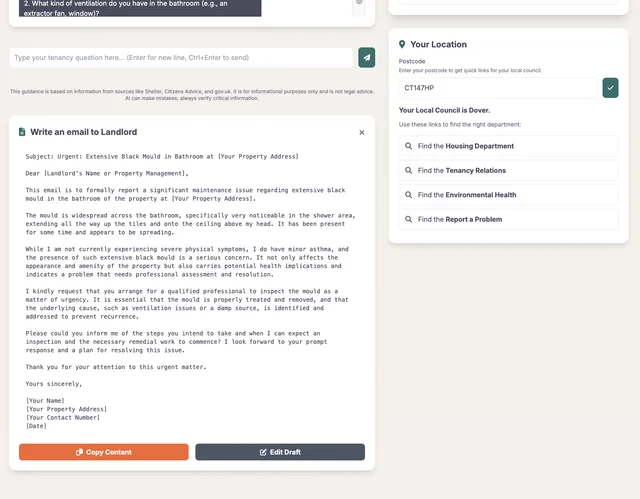
A drafted email to a landlord about mould, beside a postcode lookup for the local council.
Get a letter to your landlordEdit it, copy it and send it. A postcode finds the right council team.
Notes to prepare for a call with the council, as a list of points to cover.
Prepare for a callA list of points to cover when you phone the council.

28 asks from the LSE workshop, grouped into 9 features; 13 things declined with a public reason

In summer 2026, LSE led two think tanks with tenants, at Trafford Hall and in London. I was there for two days. Then I turned what tenants asked for into requirements.

  • Census analysis

    212,725 social renters in England cannot speak English well or at all. That set the language list: 16 on staging.

    ONS Census 2021. My analysis.

  • Real questions

    19 tenant questions, word for word, from Reddit and Facebook.

  • Tenant survey

    A survey of 400+ tenants.

    Count only. Detail not shared here.

  • Partner scoping

    Work with partners set the edges of the funded scope.

9 features built

Eight grew out of the workshop asks. One did not.

  • Quick exit and discreet mode
  • Accessibility to WCAG 2.2 AAVoice uses the phone’s own dictation and read-aloud.
  • Feedback by themeNo text is stored.
  • Other languagesChosen from census data. 16 on staging.
  • Photo evidenceAnalysed, never stored.
  • Housing-association tailoringBuilt from published policies.
  • Home-screen installNo app store needed.
  • A “What’s changing” pageOn changes to tenancy law.
  • Forced model migrationNot a workshop ask. It had to happen.

13 declined, each with a public reason

This is the exclusion list from the scope of works. The reason sits under each one. I went back on one of them, and it is marked.

  • Accounts, saved cases and remindersWould store personal data. The service is anonymous by design.
  • Email or text summariesNeed contact details. Print and copy do the job.
  • Video, voice-note and PDF uploadMore data exposure. Photos come first.
  • Live chat or a human adviserThe service is labelled as AI. It points to Shelter and Citizens Advice.Live chat: declined in the scope, then built anyway as a voice experiment. See why
  • Help outside EnglandHousing law is devolved. A signpost beats wrong guidance.
  • Tailoring to individual landlordsIt stops at housing associations, where policies are published.
  • App-store appsHome-screen install instead. No second codebase.
  • Portal and complaint-system linksThey need landlord agreements that do not exist.
  • Predicting problems earlyNeeds data kept about tenants.
  • Professional translation or bilingual legal reviewNot fundable. The site tells users.
  • Training models on user dataNever.
  • BSL videoA real need, outside the budget.
  • Marketing and tenant engagementThat is the partners’ role.

The 28 asks fell into five groups. They were accessibility and display, privacy and safety, core features, community and data, and blue-sky ideas.

Experiment on the staging site, October 2026

Talk to us: the one no I took back

The scope said no to live chat with an AI. I built a voice version on staging anyway.

Film: the Talk to us page on staging, before a call. A slow scroll over a screenshot. No sound. A recording of a real call will replace it.
What the film shows
  1. The top of the page: the Experiment on the staging site label and the Talk to us heading.
  2. The tip about the Exit this page button, in the top corner.
  3. The Talk button, with End and get my action points beside it.
  4. Sources used in this call and Behind the scenes, empty until a call starts.
  5. What was said, which reads “Nothing yet.”

Tap Talk and say what is going on with your home. The helper listens, checks the service’s own sources, and talks back. While it does, the page shows three things.

What was said
A live transcript of the call. Both sides appear as they speak.
Sources used in this call
The service’s own sources that the helper checked, listed as it uses them.
Behind the scenes
Each search of the sources, shown the moment it happens.
The Talk to us page on a phone, in dark mode: an Experiment on the staging site label, a house with a microphone, and the Exit this page tip.
Staging only

What the tenant is told

  • It is labelled “Experiment on the staging site”.
  • England only. It is an AI, not a lawyer.
  • Your voice goes to Google to be understood and answered. It is not stored.
  • Calls last up to 10 minutes.
  • “End and get my action points” makes a sheet you can print. It covers what to do, help from a person, what is still to find out, and the sources.

As shown on the staging page.

Live today, and the funded build

Same phone, same page. Here is what changes.

The live site on a phone: For private tenants in England, with a light and dark switch.
Live since October 2025

The live site

  • For private tenants in England.
  • Light and dark modes.
  • A signpost for Wales, Scotland and Northern Ireland.
The funded build on a phone: language picker, Install app, Accessibility, and an Exit this page button.
Staging, launch planned December 2026

The funded build

  • For all tenants in England, social housing included.
  • Choose from 16 languages.
  • Install it to your home screen.
  • Accessibility settings.
  • Quick exit: press the button, or Shift three times. A discreet mode too.

How we tested it

On 2 October 2026 I tested the live site and the funded build side by side.

  1. Each case ran as a full conversation.
  2. If the assistant asked questions, a simulated tenant repeated the scenario.
  3. It said “I don’t know any more details”, then “please just give me your best advice”.
  4. The assistant got up to three turns.
  5. Answers from both versions were shuffled and labelled with letters.
  6. Five Claude reviewers scored them blind, against the project’s own legal context.
A gated case fails if the answer misses a must-say point or includes a must-not-say point.
Case setCasesGatedWhat makes it different
Standard14All 14Every case is gated
Wild186Real Reddit and Facebook wording
Test506Broad coverage

Results across all 82 cases

Blind review by five Claude reviewers, 2 October 2026. One run per case. Reviewers are AI, not lawyers.
MeasureLive siteFunded build
Judged the better answer12 of 82 cases57 of 82 cases
Answers that used the wrong law20
Time to first words4.5 s2.3 s

The stack mattered as much as the model

Same day, same 50 test cases on staging, four set-ups, scored blind.

Same model, about one point apart

Set-upAverage score out of 5
3.8 Flash, low thinking (staging)
4.56
2.5 Flash (staging)
3.64
2.5 Flash (live site)
2.66
Flash-Lite, two set-ups (staging)
2.48 to 2.56
Blind review, 2 October 2026, same 50 test cases. The live-site row comes from the baseline run that day.

What this shows, and what it does not

  • The point to take away. 2.5 Flash scored about one point higher on staging. Retrieval and the prompt made that difference, not the model.
  • Flash-Lite looped. It kept asking “who is your landlord” when the tenant skipped the welcome screen.
  • I got the rubric wrong once. It marked lock-changing advice as unsafe. That caused four false hard fails in this comparison. I corrected it.
  • AI reviewers, not lawyers. They score against our legal context, not a solicitor’s view.
  • One run per case. A second run could move the scores.
  • The simulated tenant has limits. It cannot answer questions its scenario does not cover.

Trade-offs I chose

Each one gave something up. Here is what, and why.

Anonymous, so no memory

No accounts means no saved history. Tenants keep a copy by printing or copying.

England only

Housing law differs in Wales, Scotland and Northern Ireland. A signpost beats wrong guidance.

The phone’s voice, not a server’s

Every phone already has dictation and read-aloud. Server speech would cost about 13 times the answer itself. No audio reaches the service, so there is no new privacy risk.

The Talk to us experiment is the exception. Its audio goes to Google, and is not stored.

Questions first, at a cost

Asking first should fit the advice to the case. But 21 of 82 live test chats never reached advice.

Vector search, then hybrid again

Version 1 logs showed the 0.5 similarity cut-off never filtered anything. Vector search alone also missed exact terms, such as Section 21 versus Section 8. Version 2 fuses full-text and vector search.

One slow query, fixed

A retrieval query fell from 2,911 ms to 136 ms. That is 21 times faster.

Measured with EXPLAIN ANALYZE, May 2026.

Tenants only, not landlords

Landlords already have access to legal help. Tenants often do not. Landlord questions get a pointer elsewhere. Some questions sit in between, and those can go wrong.

Accuracy before speed

For legal guidance, a wrong answer is worse than a slow one. Accuracy is checked against an evaluation set; it is not guaranteed.

One function, one database

One Supabase Edge Function and Postgres with pgvector, not a team of agents and a separate vector store. Fewer parts means fewer things to break.

What comes next

  • Planned
    Public launch of the funded build, planned for December 2026.
  • Planned
    A dissemination year with the partners, to December 2027.
  • Planned
    Content for social-housing tenants, tested with a tenant panel.
  • Planned
    A report after 12 months.

Known limits

What it does not do, said plainly.

  • England only. Other nations get a signpost.
  • Guidance, not legal advice. The site says so under the chat.
  • No professional translation. It was not fundable, and the site tells users.
  • Tested by AI reviewers, with one run per case.
  • No BSL video yet. It is a real need, outside the budget.

Deep dives: the build log

I wrote these up as I built, from 2025 to May 2026. Each one says what broke, what I changed and what it cost. Some later parts undo earlier ones, and say so.

Where it started

A landlord tried to keep £2,625 of my partner’s deposit. We used NotebookLM on official guidance to argue back, and got £2,350 returned.

But people did not trust general AI with legal questions. NotebookLM also pulled from wrong sources. So I built a tool on official sources only.

The deposit dispute that started the project, decided by the Tenancy Deposit Scheme before this tool existed.

How it is built

Search covers official sources only: gov.uk, Shelter, Citizens Advice and the Tenancy Deposit Scheme. Documents are split into chunks with a recursive text splitter.

There are no accounts or sign-up. Chat history stays on the tenant’s device.

I traded speed for accuracy. Accuracy is checked against an evaluation set; it is not guaranteed.

How an answer is made

Five steps, on the live site and on the funded build.

Live site, May 2026 code

  1. The question, on its ownChat history is not added to the search.
  2. Embeddinggemini-embedding-001 turns it into numbers.
  3. Vector searchpgvector with an HNSW index finds the top 5 matches.
  4. Legal context firstA block of current law sits above the matches.
  5. Streamed answergemini-2.5-flash writes it. A second call adds action buttons.

Funded build on staging, October 2026

  1. Question rewrittenIt becomes a standalone English question, so “tell me more” works.
  2. Embeddinggemini-embedding-2.
  3. Hybrid searchFull-text and vector results, fused with RRF.
  4. Legal context firstThe same block of current law.
  5. Streamed answer3.8 Flash, low thinking.
Redrawn October 2026. The 2025 diagram showed a keyword step, an older embedding model, chat history in the search and a JSON reply. Parts 3, 6 and 7 removed them.
  1. Part 1Performance

    A slow query and the wrong index

    One database call took most of the query time. The right index, and a filter before the search, fixed it.

    Read part 1
    What broke
    One call, match_documents, took 68.2% of all query time. It averaged 911 ms and peaked at 2,620 ms.
    Why
    The vector index measured L2 distance. The embeddings needed cosine similarity, so the index went unused. Every search scanned all the documents, and a keywords column sat idle.
    The fix
    A new index built for cosine similarity. A GIN index on the keywords. The search filtered by keyword first, then ran the vector search on what was left.
    Result
    Mean time fell from 911 ms to about 37 ms, about 24 times faster. Peak time fell to about 40 ms.
    Lessons
    Filter first, then search. Match the index to the distance your embeddings use. A 100% cache hit rate meant the problem was compute, not disk. Measure each layer: the next bottleneck was slow AI calls.
    Since then
    Part 3 removed the keyword step. By May 2026 a new, larger corpus had no vector index at all. Part 5 picks that up.

    Database query logs, 2025, on the 2025 corpus of about 6,000 documents.

  2. Part 2Stability

    Long chats crashed the app

    The most engaged users hit a crash. The embedding model had a size limit, and long chats broke it.

    Read part 2
    What broke
    The core function failed with a 400 error. People with long, detailed chats hit it most. They were the most engaged users.
    Why
    The embedding model, text-embedding-004, takes about 36,000 bytes. The code sent it the whole chat history.
    The fix
    Two histories. A short, recent one went to the embedding for search. The full one went to the chat model, gemini-2.5-flash, for context.
    Since then
    Part 7 reversed this in May 2026. The recent history was skewing the search. Now only the question is embedded.
  3. Part 3Speed and stability

    A slow step that did not earn its place

    An AI step that wrote search keywords was by far the slowest part. Removing it fixed the speed, and later cost some accuracy.

    Read part 3
    What broke
    Answers took over 40 seconds. The function also crashed with a 500 error when the AI replied in plain text instead of JSON.
    Why
    The JSON parse had no error handling. And an AI call to write a search query and keywords took 27.7 seconds. The database search itself took 250 to 1,100 ms.
    The fix
    Catch the parse error and show a friendly fallback message. Drop the keyword step. Embed the question and recent chat, and run a vector-only search.
    Result
    Server time fell from about 41 s to about 3.8 s. I compared answers side by side by hand and saw no clear drop in quality. I did not record how many I compared.
    Lessons
    Always have a fallback for AI output. Question every expensive step. Removing a step can beat tuning it.
    Since then
    Vector-only search missed exact terms, such as Section 21 versus Section 8. In May 2026 the legal context block in Part 10 became the safety net. Hybrid search returned on staging in October 2026, after logs showed the 0.5 similarity cut-off never filtered anything.

    Server timings, 2025, on the 2025 stack. This is not today’s response time: on 2 October 2026 the live site took 4.5 s to its first words.

  4. Part 4Usability

    The Enter key sent half a thought

    People typing a longer answer sent it too early. A text box that grows as you type fixed it.

    Read part 4
    What broke
    The assistant asked for details. People pressed Enter for a new line, and half an answer went off. The assistant then asked the same questions again.
    Why
    A one-line input box sent on Enter. It fought what people were trying to do.
    The fix
    A multi-line box that grows as you type. Sending moved to Ctrl+Enter or Cmd+Enter. The placeholder text explained the change.
    Since then
    On the funded build, phones treat Enter as a new line and send with a visible button. No feature depends on a keyboard shortcut.
  5. Part 5Performance

    Indexing 3,072-dimension embeddings

    There was no vector index at all. An HNSW index on a half-precision cast stopped the timeouts.

    Read part 5
    What broke
    Some chats failed with a statement timeout. The database role allowed 3 seconds. A cold query took 2,911 ms, right at the edge.
    Why
    No vector index existed. Every search scanned 3,374 rows of 3,072-number vectors. And pgvector’s HNSW index only takes 2,000 dimensions on the standard vector type.
    The fix
    Build the HNSW index on a cast to halfvec, which stores half-precision numbers and allows 4,000 dimensions. Cast both sides of the search the same way, so the planner uses the index. The column stayed as it was, so nothing was re-embedded.
    Result
    The same query fell from 2,911 ms to 136 ms, 21 times faster. Buffer reads fell from 47,851 to 690. The timeouts stopped under normal load.
    Lesson
    The 2,000-dimension cap is easy to miss. If your embeddings are large, plan the index on day one.

    EXPLAIN ANALYZE on the same probe query, 18 May 2026.

  6. Part 6User experience

    Streaming: words on screen while the answer is written

    People stared at a spinner while the answer was written. Streaming gave them something to read sooner.

    Read part 6
    What broke
    Answers took about 10 to 15 seconds, with only a loading ring on screen. Past about 10 seconds, people drift away.
    The fix
    The server streams the answer as it is written, as server-sent events. A separate call adds the action buttons. In the browser, a typewriter paces the text frame by frame, so it moves smoothly, not in bursts.
    Result
    The first words appeared at about 12 s, not 15 s. The screen updated every 17 ms on median, too fast to look stuck.
    Lesson
    A wait you can watch feels shorter. You cannot always cut the wait, but you can make it readable.
    Cost
    The browser had to read the stream with fetch, not the SDK’s helper. Front end and back end now deploy together. During the rollout, chat broke for one to two minutes.

    One test answer of 5,024 characters, May 2026. On 2 October 2026 the live site took 4.5 s to its first words.

  7. Part 7Reliability

    When the fix becomes the bug

    A tenant changed topic and the bot refused. Replaying the chat with real numbers showed the search was stuck on the old topic.

    Read part 7
    What broke
    A tenant asked about deposits, then about Awaab’s Law. The bot said it only had deposit information. After pushback, it answered.
    Two guesses
    Either chat history was skewing the search, or the model gave in and answered from memory. Guessing would not pick the right fix.
    What I did
    I added a debug mode, off in production, that reports what the search saw. Then a short script replayed the exact five-turn chat.
    What it showed
    By turn 3 the search input was mostly the earlier deposit answer. All five matches were about deposits. Awaab’s Law sources appeared only at turn 5, once old messages dropped out. The bot had refused correctly.
    The fix
    Embed only the current question. The chat model still gets the full history.
    Result
    The same Awaab’s Law question now finds five Awaab’s Law sources and answers first time.
    Since then
    This reversed Part 2. Choices have a shelf life. Follow-ups like “tell me more” lost their topic. On staging, in October 2026, a rewrite step brought them back.

    Replay of one reported conversation, May 2026.

  8. Part 8User experience

    Errors in plain words

    Raw database errors reached users. Now each failure maps to a sentence people can act on.

    Read part 8
    What broke
    A failed request showed text like “canceling statement due to statement timeout” in the chat. Rate limits, safety blocks and quota errors leaked raw text too.
    The fix
    The server sorts every failure into a fixed code, such as RATE_LIMITED, CONTENT_BLOCKED or DB_TIMEOUT. Errors mid-stream arrive as events, so the half-written answer stays. The browser maps each code to a plain sentence. Short blips retry once, then show a Retry button. On load, a check shows a banner if the site’s settings are broken.
    Result
    Timeouts and blocks became one sentence the user can act on. Most short blips fix themselves.
    Lesson
    Treat errors as part of the product. Write the friendly wording once, in one table.
    Cost
    The sorting matches error text. If a provider rewords its errors, it breaks. I queued a test for each known failure.
  9. Part 9User experience and reliability

    Listen before you advise

    Long answers built on guesses gave way to short questions first. Testing later showed what that cost.

    Read part 9
    What broke
    Every question got a long procedure, often built on guesses about tenancy type, nation or landlord. A confidence badge said “High” even on refusals. The page then folded long replies away.
    Why
    The prompt rewarded long answers. “Ask if you are not 95% sure” did not work: the model nearly always felt sure. The badge was not tied to any evidence.
    The fix
    Three modes with hard triggers. If key facts are missing, ask two or three short questions. For a pure law question, give a short definition. Give full steps only once the facts are in, or the tenant asks. The badge and the folding went.
    Result
    “My landlord won’t fix the heating” now gets three questions, not 40 lines. In a smoke test, 8 of 10 questions hit the expected mode first time.
    Lesson
    A confidence number nobody can check is worse than none.
    Measured cost
    The triggers fired too often. On the live site, 21 of 82 test chats never got past questions. The funded build asks two optional welcome questions, nation and landlord, and passes them on. None got stuck.

    Smoke test: 10 hand-picked questions, Claude Sonnet 4.6 as judge, May 2026. Stuck chats: blind evaluation, 2 October 2026.

  10. Part 10Reliability

    Anchoring the model in current law

    The bot described Section 21 as current after it was abolished. A short block of checked facts now sits above every answer.

    Read part 10
    What broke
    The Renters’ Rights Act 2025 abolished Section 21 evictions in England from 1 May 2026. The model and the stored documents both predated it. So the bot called Section 21 the normal way to end a tenancy.
    Why
    Two layers were out of date: the model’s training and the documents. Better search cannot fix wrong sources. I had stored each document’s date in 2025, but dates alone did not stop stale advice. Nothing told the model that new law beats old guidance.
    The fix
    A legal context block above the search results. It covers the Act’s key dates and rules, and what is not yet in force. It also says the Act is England only. One rule: if a source disagrees, trust the block and say the source is out of date. I checked every fact against gov.uk and Shelter on the day.
    Result
    Asked about Section 21, the bot now says it was abolished from 1 May 2026. It also explains the rule for older notices. It flags old sources instead of repeating them. The block adds about 280 tokens to each question.
    Lesson
    When the world moves past your model’s training, a short block of checked facts beats a retrain. The rule about which source wins is what makes it work.
    Cost
    Someone has to keep it current. I set a limit of about 10 facts before moving them to a database table. By October 2026 it held about 20.

    Prompt size measured May 2026. Block size counted October 2026.

Run a housing service or an advice line?

Tell me what your tenants need. I read every message.